Benchmarking AI Models for Legal Applications
A practical examination of contract extraction, citation accuracy and research coverage—and what each reveals about model quality.
Read the research report ↗Sridhar Ramachandran · CEO & Co-founder · October 2026
TL;DR
Related white papers · CORTEGA LABS
Explore the full research library ↗Last week I wrote about Jev, TypeSafe AI's new “decision model.” Not surprisingly, this week there's already an open-source close follower: Kev, built by Jared Palmer on top of Alibaba's Qwen3.5.
Both are the same basic idea, and it's the idea that matters for hallucination: neither model writes free text. Feed either one a document and a set of yes/no or multiple-choice questions, and it returns a calibrated probability for each option. No free text to be generated, hence no hallucination. But that doesn't prevent either model from being confidently wrong.
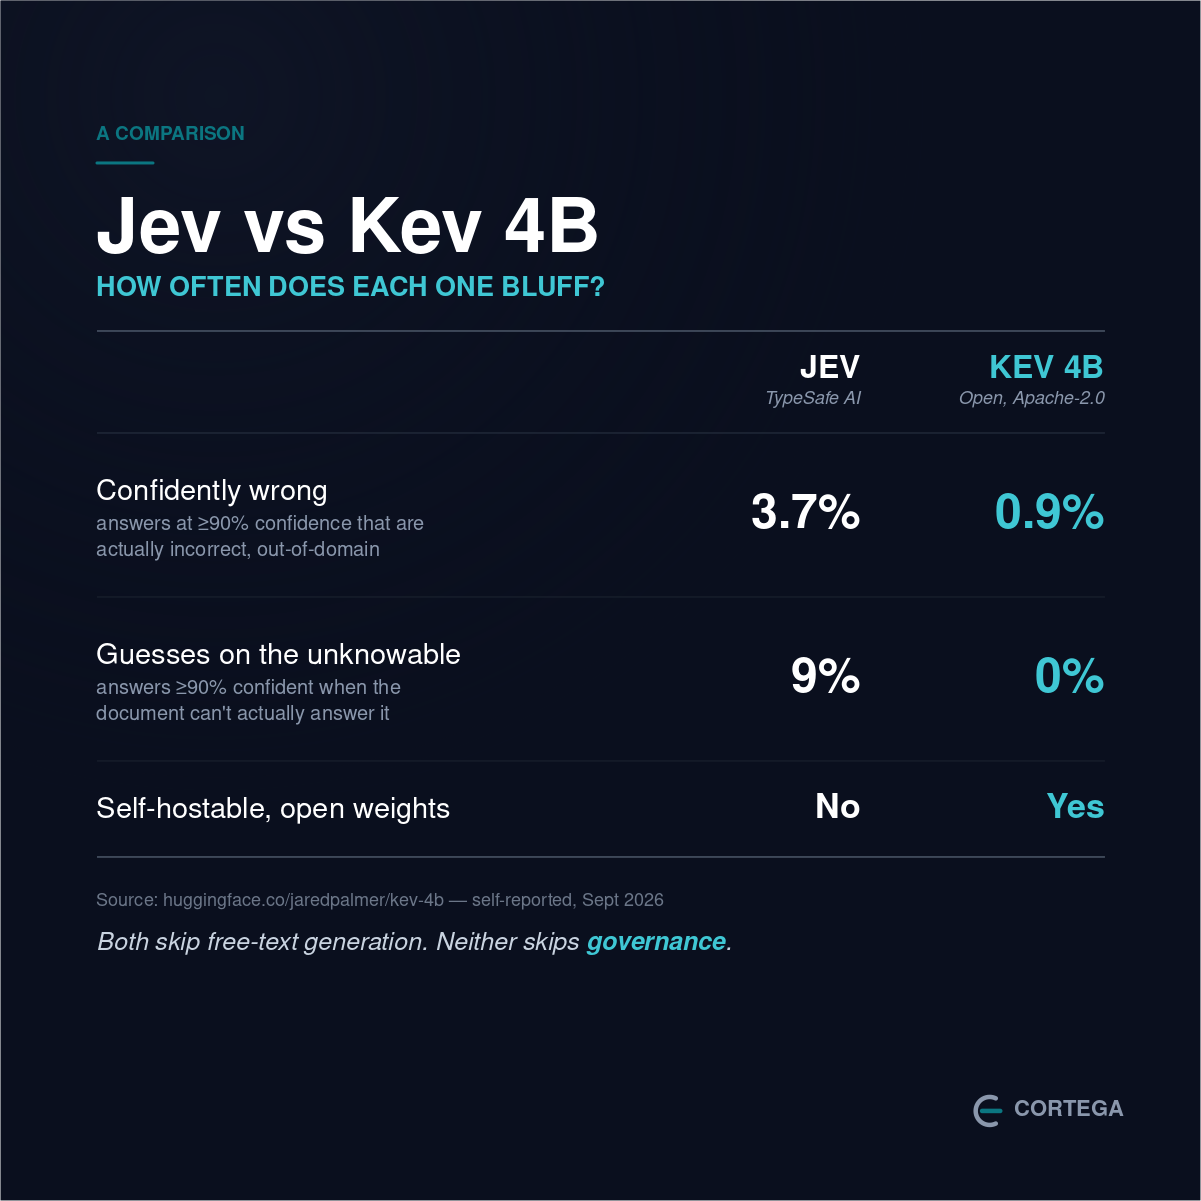
Kev's case is that it's open-weight and self-hostable (Apache 2.0), and its builder has been shipping improved checkpoints almost daily. I am sure Jev will keep improving too.
We support both decision models at Cortega, especially in classification use cases, such as legal eDiscovery. Whichever decision model you pick, it still has to run somewhere, under somebody's data policy, with a record of what it saw and what it returned. The agent using the decision model still needs to be secured and governed.
Originally posted on LinkedIn. · Back to all posts
MAKE YOUR NEXT MOVE
Explore how Cortega fits your AI environment.