AI Model Comparison
Model comparison by workload
The Model Recommender ranks a curated catalog against your workload, team size, and priorities. Every result carries public benchmark evidence and compares against the model you run today.
The Model Recommender ranks a curated catalog against your workload, team size, and priorities. Every result carries public benchmark evidence and compares against the model you run today.
Pick the workloads you run and the number of people they serve.
Requests per month and tokens per request, pre-filled from your workloads and editable.
Name the model you run today. Recommendations must meet or beat it on capability.
Weight what matters: quality, cost, coding, reasoning, chat, speed, or tool use.
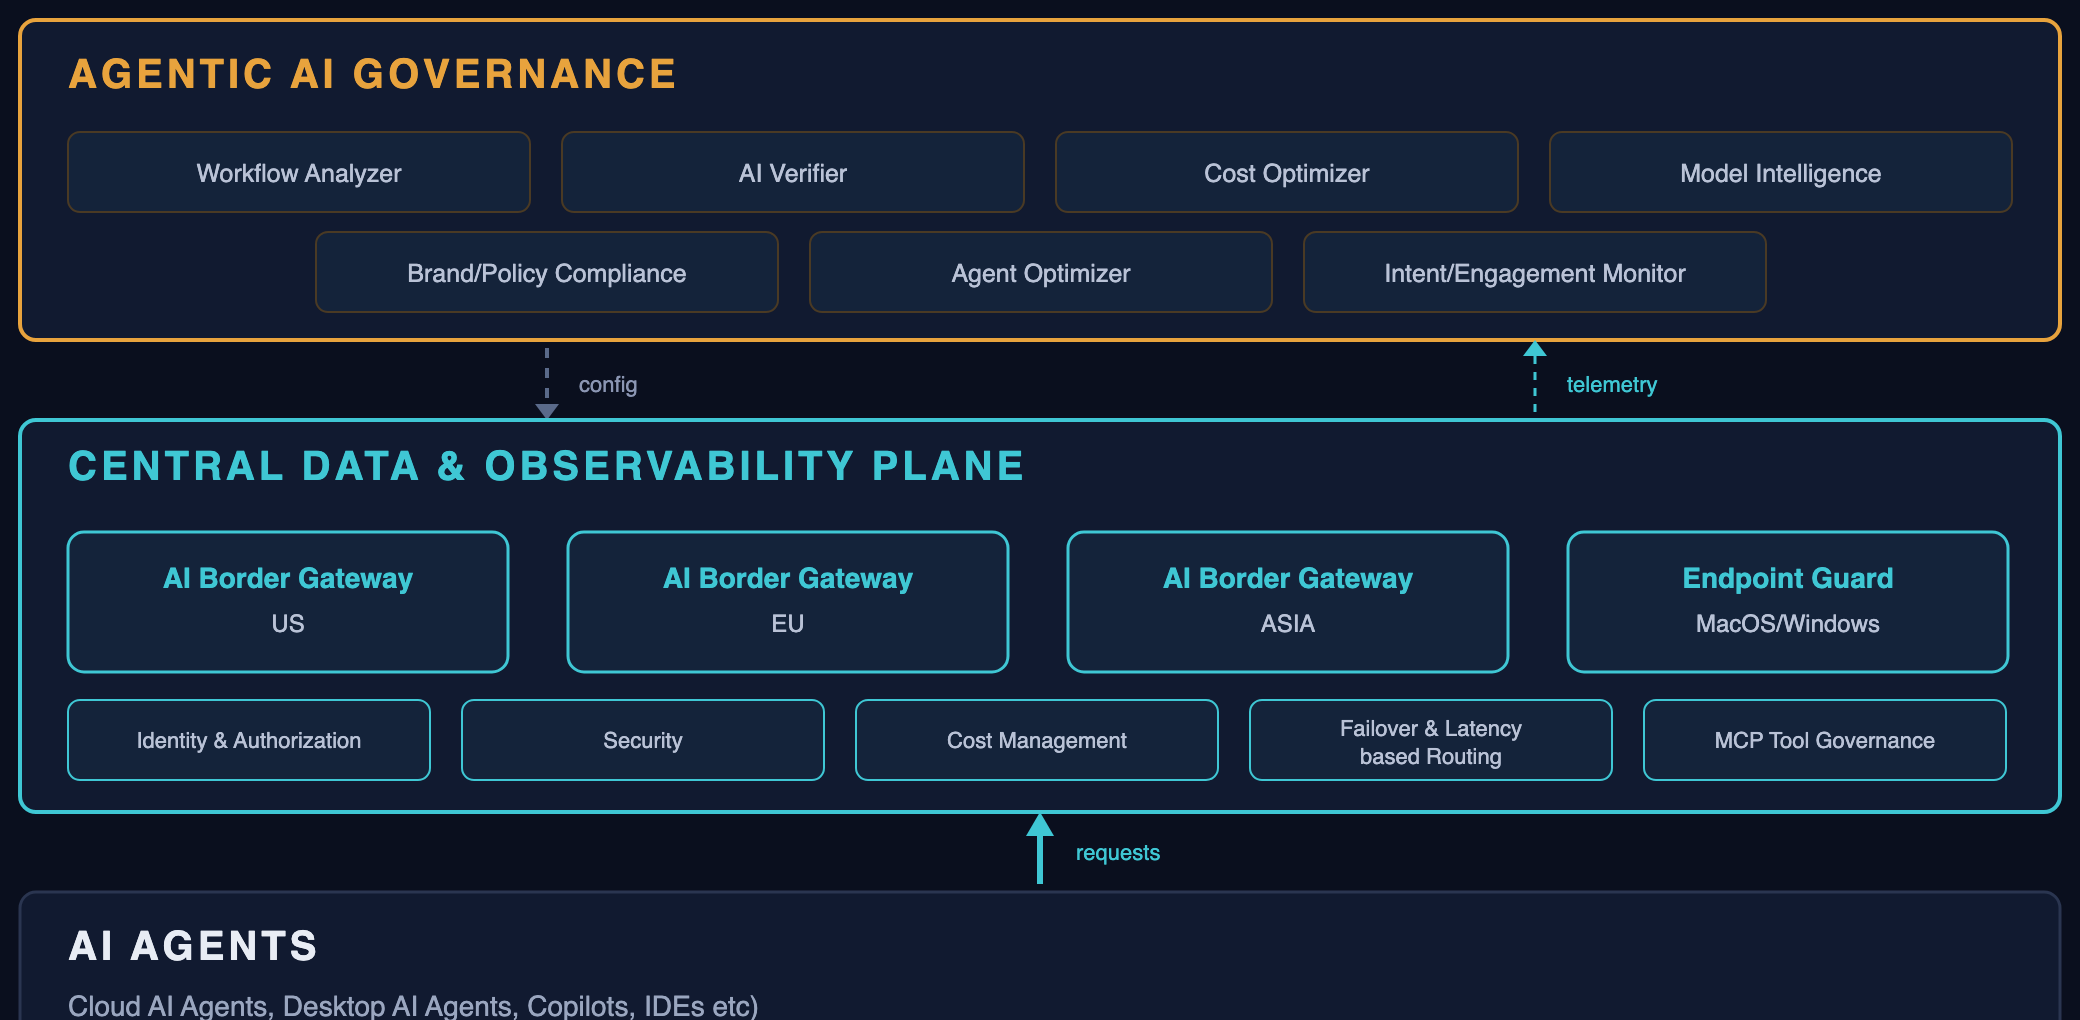
Pick a model here, then configure it as a routing target in your gateway.
AI Border Gateway →Rankings are backed by public benchmarks, so a result is something you can check.
Put the models that fit into weighted, failover, or conditional routing, enforced at the gateway.
AI Border Gateway →MAKE YOUR NEXT MOVE
Explore how Cortega fits your AI environment.