This is a follow-up to A Research Plugin Is Not a Citation Check. The thesis for that post was: feeding a model more primary law is not the same job as independently looking up the cites it already claimed. In this post we provide examples based on OpenAI's recent litigation prompts that were used to announce Astra for Law.
OpenAI published litigation prompts with Astra for Law. The first: find the closest factual precedent and write a memo on a private-label misrepresentation claim.
We ran that prompt on Llama 3.3 70B and Claude Sonnet 4.5, then put Cortega AI Verifier on the output.
The findings
Llama without a check is easy to dismiss. Claude without a check is the one a firm should worry about. It looks like a memo. Sections, counterarguments, next steps. The cites still fail a lookup and a relevancy check.
| Run | Cites checked | Confirmed | Flagged |
|---|---|---|---|
| Llama 3.3 70B, no check | 14 | 2 | 12 |
| Claude Sonnet 4.5, no check | 15 | 7 | 8 |
Flagged means fabricated, name-mismatched, not in the verification index, or a real opinion that does not support the claim. We did not run Astra. OpenAI compared Astra to a different Claude release than the Sonnet 4.5 we used.
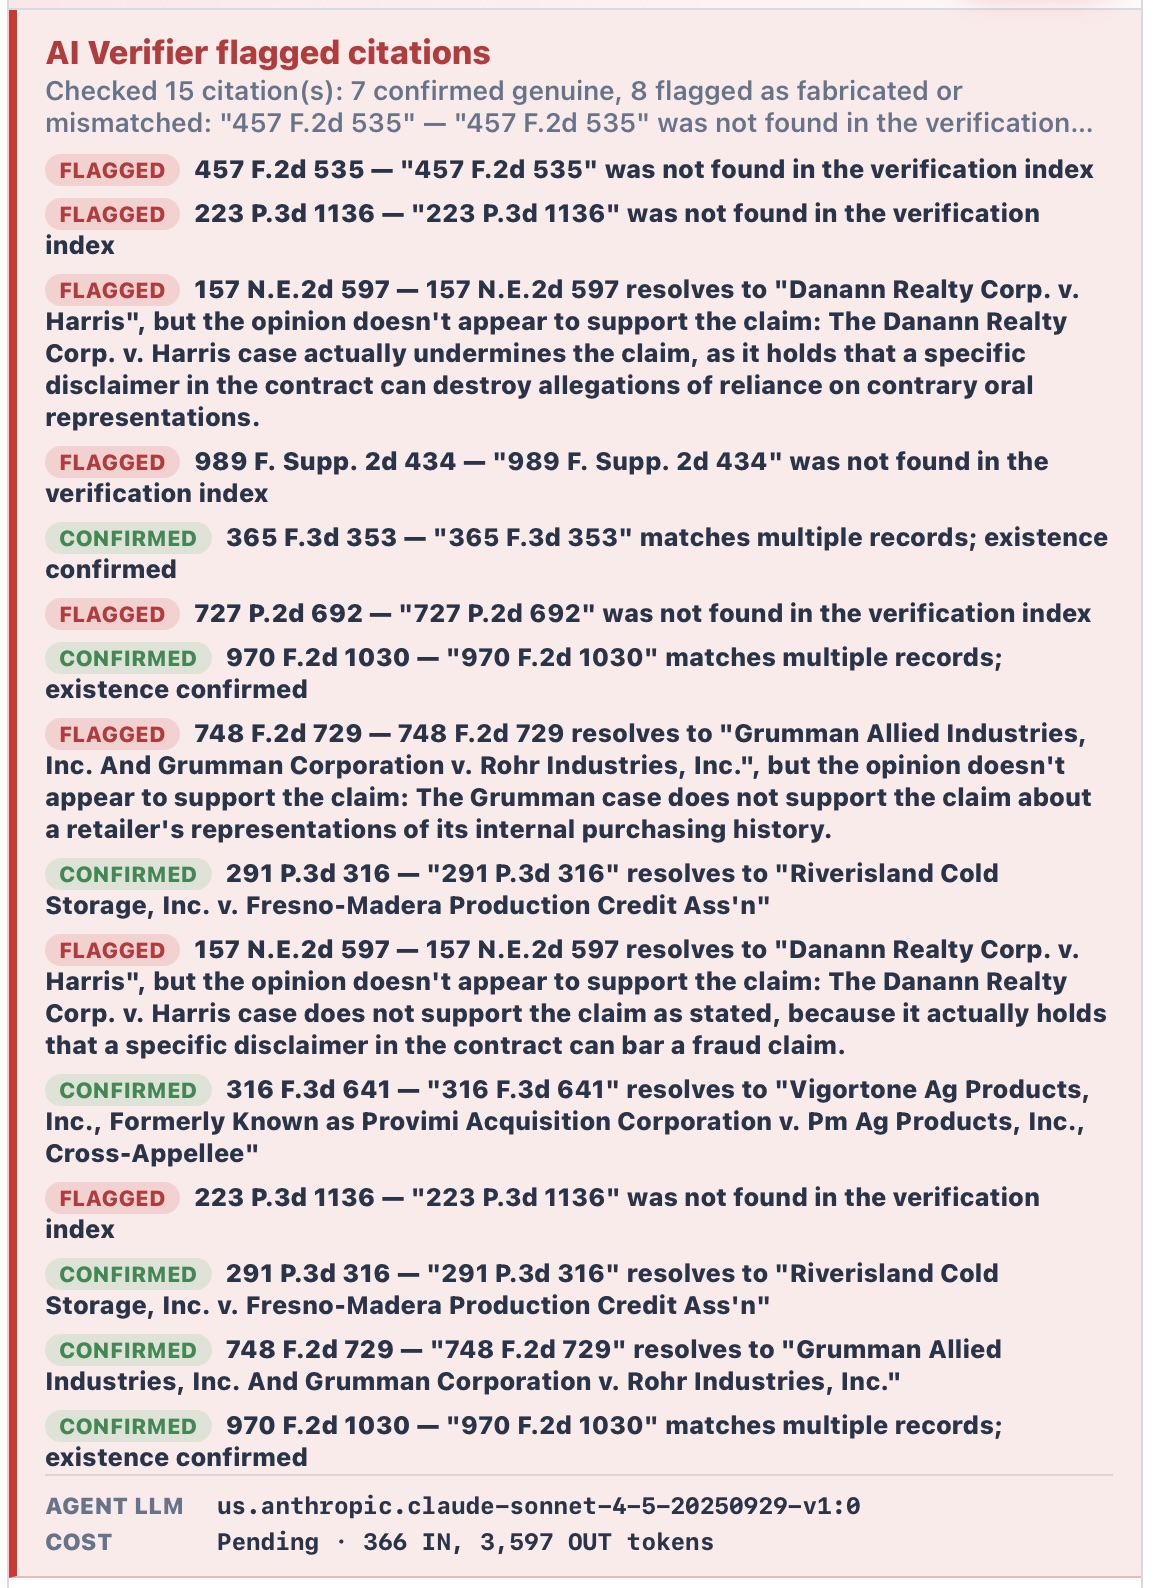
The Claude run on the private-label prompt. 8 of 15 cites flagged. Arena report (PDF).
The flags
- Llama, bare. Spano v. Perini Corp., 25 N.Y.2d 11, cited for fraudulent inducement. The opinion is about absolute liability in blasting. Real case, wrong doctrine.
- Claude, bare. Industrial Polymer Solutions, 989 F. Supp. 2d 434, sold as the closest / strongest precedent. Not found in the verification index.
- Claude, bare. Danann Realty Corp. v. Harris, 157 N.E.2d 597, cited as if extra-contractual representations still support fraud. The Verifier: the opinion actually undermines the claim. A specific disclaimer can destroy reliance on contrary oral representations. Real case, opposite holding.
- Claude, bare. Grumman Allied Industries v. Rohr Industries, 748 F.2d 729, cited for reliance on a retailer’s internal purchasing history. Real case. The opinion does not support that claim.
A typical ChatGPT plugin does not catch these. I want to point out Danann: it exists. However, it does not support the proposition. This is exactly what we pointed out in the previous post: Stanford RegLab and HAI already measured that pattern on RAG legal research tools.
The Delaware prompt
The same Astra page also published a stockholder challenge. The board approved an asset sale over a holiday weekend after receiving hundreds of pages the day before. Directors were told the buyer’s financing would expire that weekend. The buyer had requested that deadline, and its lender was willing to extend it. Find the closest Delaware precedent and write a memo.
We ran that one on Claude Sonnet 4.5, then put Cortega AI Verifier on the output.
| Run | Cites checked | Confirmed | Flagged |
|---|---|---|---|
| Claude Sonnet 4.5, no check | 6 | 4 | 2 |
Four of the six cites resolved. Two were real Delaware opinions used for a proposition the opinion does not support.
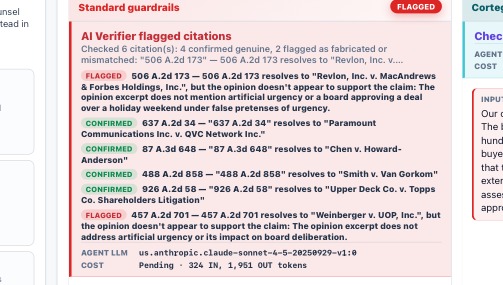
The Claude run on the Delaware prompt. 2 of 6 cites flagged. Arena report (PDF).
The Delaware flags
- Claude, bare. Revlon, Inc. v. MacAndrews & Forbes Holdings, Inc., 506 A.2d 173, cited for artificial urgency and a holiday-weekend board approval. Real case. The Verifier: the opinion does not mention artificial urgency or a board approving a deal over a holiday weekend under false pretenses of urgency.
- Claude, bare. Weinberger v. UOP, Inc., 457 A.2d 701, cited for entire fairness / unfair dealing from that urgency. Real case. The Verifier: the opinion does not address artificial urgency or its impact on board deliberation.
Same pattern as Danann. Paramount, Chen, Van Gorkom, and Topps resolved. The two flags still exist. They do not support the proposition Claude used them for.
Our Claim
We are not claiming Llama plus a check is Astra. We are not claiming Sonnet is unusable. We are claiming the writing model, cheap or frontier, still needs an independent look at the cites after the answer is written.
AI Verifier sits outside the tool. It looks each answer up against U.S. case law, federal regulations, patent grants, and Canadian legislation, then asks whether the opinion supports the claim. If the cite is invented or off-point, it asks the original model to drop it and not invent a new one, then re-checks. Inline, or alert-only on the laptop.
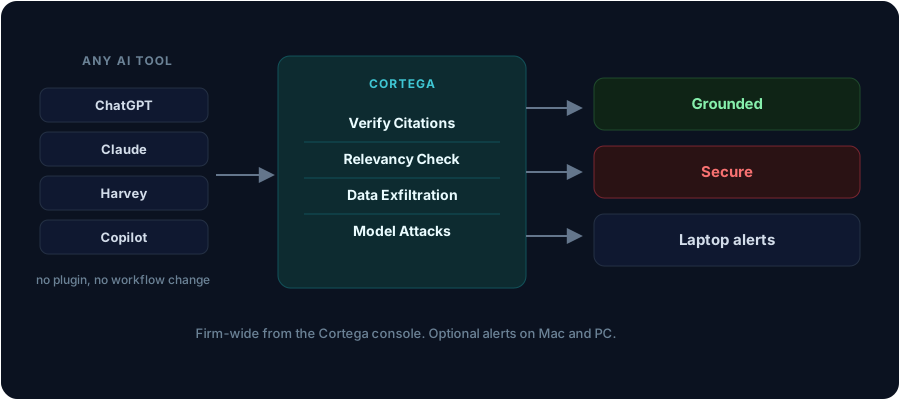
We have a live demo. Paste a brief, or use either of OpenAI's prompts, and watch the flags: arena.cortega.ai/enterprise/hallucination. The product page for firms is Verify citations in every AI tool.
If this is the model your team already uses, we will run the same prompt on that traffic in a briefing.